Home / Infrastructure & Protocols
How Search Engines Index the Web: Crawling, Indexing, and Ranking in Milliseconds
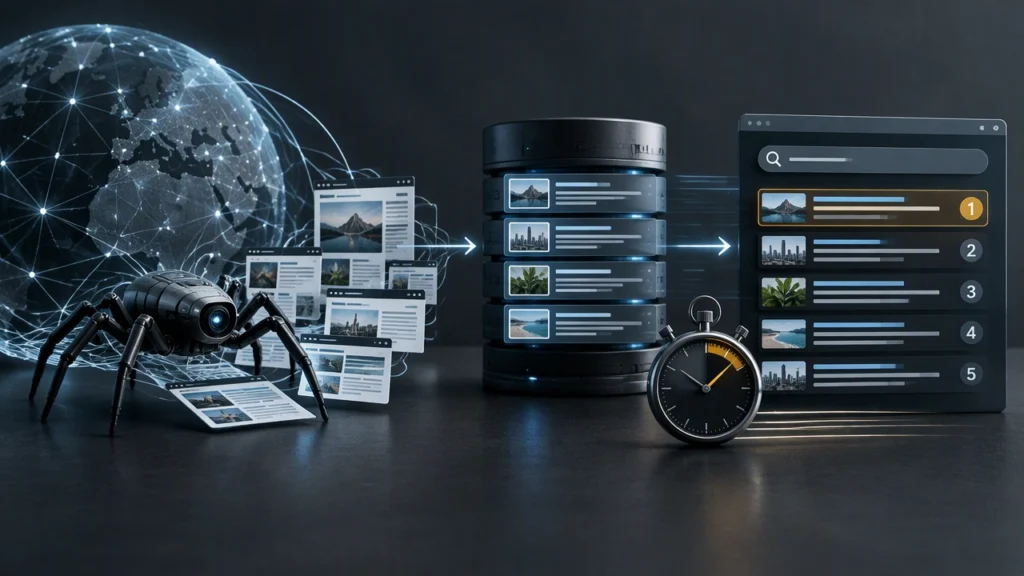
When you type a question into a search box and get useful results in milliseconds, you are seeing the output of a large distributed system designed to discover web pages, understand them, store key information, and select the best matches almost instantly. That system sits inside the wider world of web services, but its core job is narrow: make the public web searchable at scale.
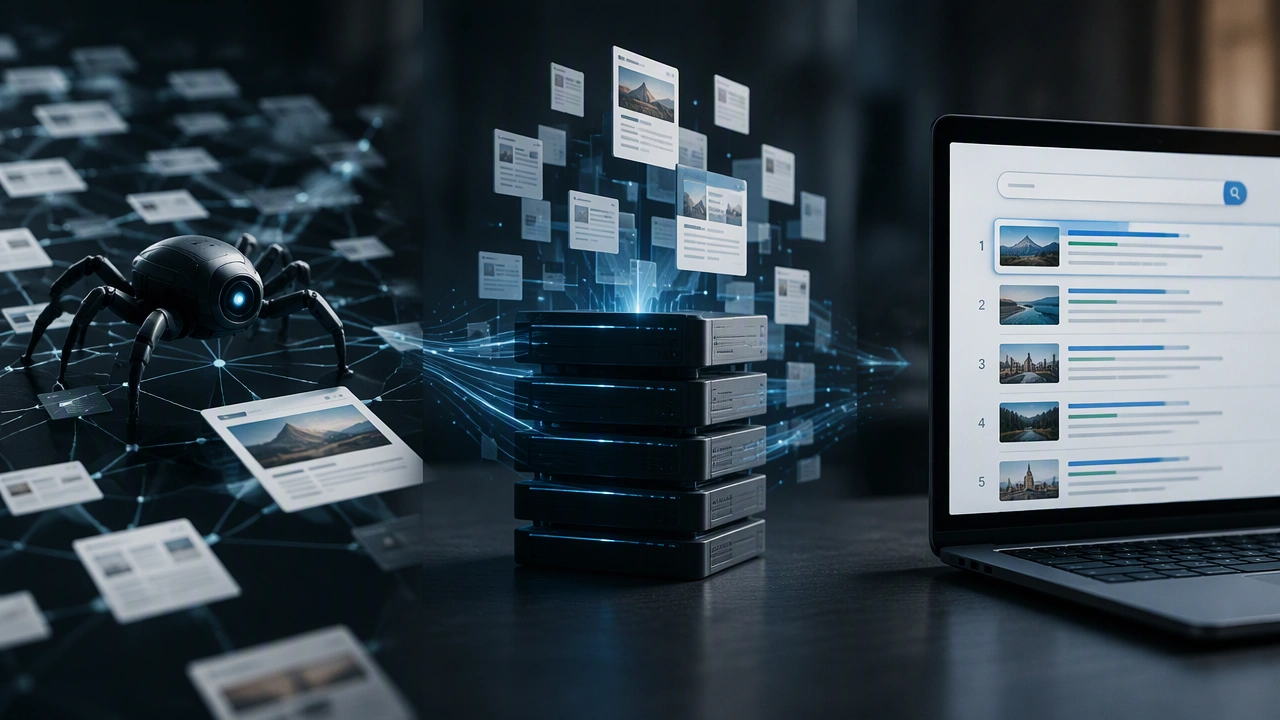
People often ask how do search engines crawl and index websites. The short answer is that they discover pages through links, fetch them with specialized crawlers, extract text and metadata, normalize and store that information in a massive index, and then use ranking signals to decide which pages should appear first for a given query.
Crawling: discovering and fetching pages at scale
Crawling begins with seeds. A search engine starts with a set of known URLs, including homepages, sitemaps, and previously discovered pages. From there, automated programs known as crawlers, spiders, or bots follow hyperlinks from page to page. Each discovered URL is queued, prioritized, and fetched like any other web request, but with strict limits and safeguards.
A crawler requests a page using HTTP, downloads the HTML, and often retrieves linked resources needed to understand the page, such as CSS, JavaScript, images, and video files. Because the web is enormous, crawlers do not fetch everything at once or with equal priority. They re-crawl pages based on perceived importance, update frequency, and server capacity. They also respect rules set by site owners, including directives that say which paths may be fetched and how often.
Crawling is not just downloading. It includes handling redirects, managing cookies, rendering JavaScript when needed, and detecting duplicate URLs that lead to the same content. It also requires politeness policies: rate limits, backoff when a server is slow, and identification through a consistent crawler name. These controls help keep the web usable while still allowing the index to stay fresh.
How crawlers decide what to fetch next
Crawlers use a priority queue. Signals include link depth, historical update frequency, page quality signals, and whether a URL appears in important sitemaps or feeds. Pages that change often, such as news homepages, are visited more frequently. Pages that rarely change may be revisited less often. This scheduling is one reason search results can reflect new content quickly without overwhelming any single website.
Rendering and understanding page content
Modern pages often rely on client-side JavaScript to build their final content. A search engine may first download the HTML and then run a second pass to render the page in a headless browser environment. This rendering step helps the system see the same content a user would see after scripts run, including dynamic menus, loaded text, and content revealed by user interaction.
After rendering, the system extracts the meaningful parts of the page: headings, paragraphs, lists, links, images, video, and structured data. It also collects metadata such as titles, descriptions, language, and viewport settings. The goal is to turn a visual page into structured information that can be stored, compared, and retrieved efficiently.
Indexing: turning pages into searchable information
Indexing is the process of organizing crawled content so it can be found quickly. The central idea is an inverted index. Instead of listing pages and then searching them one by one, the system stores a mapping from words and phrases to the pages that contain them, along with context like where the term appears, how often, and in what kind of element.
To build this index, the system tokenizes text, removes noise, normalizes forms, and links related concepts. It records positions so it can later evaluate phrase matches and proximity. It also stores metadata that helps with filtering and ranking, such as language, freshness, region, and whether the page uses HTTPS.
Deduplication and canonicalization
Large parts of the web are duplicated. The same article may appear on multiple domains, or a site may serve the same content through different URL parameters. Indexing systems detect near-duplicates and choose a representative version, often called the canonical URL. This step reduces redundancy and helps ensure that the most useful version of a page is the one returned to users.
Ranking: selecting the best results in milliseconds
When a user types a query, the system does not scan the whole web. It looks up the query in the index, collects candidate pages, and runs a ranking process to order them. Ranking blends many signals. Classic signals include the words on the page, the words in links pointing to the page, and the freshness of the content. Modern systems also use semantic understanding to match meaning, not just exact words.
Ranking is fast because most work happens before the query arrives. The index is built ahead of time, key statistics are precomputed, and candidate retrieval is highly optimized. At query time, the system narrows a huge collection to a manageable set, scores candidates, and returns a ranked list with snippets that help a user decide which result to click.
Signals that often matter
- Relevance: whether the page content matches the intent behind the query
- Authority: evidence from links and other references that the page is trusted
- Freshness: how recently the content was created or updated
- Experience: page quality, usability, and accessibility
- Context: location, language, device, and search history when appropriate
Speed: how results arrive in milliseconds
Speed comes from a mix of engineering choices. Indexes are sharded across many machines so queries run in parallel. Frequently searched results are cached. Data structures are compact and optimized for fast lookup. Network paths are short because index partitions are placed close to users in multiple regions. Together, these choices let the system go from a raw query to a ranked result page in well under a second.
Keeping the index fresh
The web changes constantly. New articles appear, products go in and out of stock, and pages are edited. Search engines balance freshness with stability by re-crawling important pages more often, prioritizing sources that regularly publish reliable updates, and detecting sudden bursts of activity that signal breaking news. When major events happen, crawling and indexing workflows adapt to capture new information quickly.
What site owners can do to help
While the system is automatic, site owners can make crawling and indexing smoother. A clear sitemap helps crawlers discover pages. Consistent URL structures reduce duplication. Serving fast, stable pages lowers crawl errors. Descriptive titles, headings, and alt text help the system understand content. Avoiding deceptive practices keeps pages eligible to appear in results.
Bottom line
Search engines answer queries quickly because they prepare in advance. They crawl the web continuously, render and understand pages, build a structured index, and apply ranking logic that balances relevance, authority, freshness, and context. The result is a system that can take a few words from a user and return a useful set of pages in milliseconds.